Xiao Yang
About
I am a Research Director at Canva on Efficient AI (Image/Video/LLMs). My goal is making Generative AI more efficient and accessible, for both inference and training.
Prior to that I worked at Bytedance as a Senior Staff Manager, managing a team of 10+ people on AIGC foundation model development and applications. Before that I also worked at Meta shortly on video advertisement products.
I got my Ph.D degree from Computer Science department, UNC Chapel Hill, advised by Dr. Marc Niethammer; I obtained my bachelor degree in Electrical Engineering from Tsinghua University.
My past works spans across various aspect of generative models, including:
- Efficient model: FlashGaze, Helios, FSVideo, SDXL-Lightning, AnimateDiff-Lightning
- Foundation models: SplitMoE, Seeddream, zero-terminal SNR, MVDream
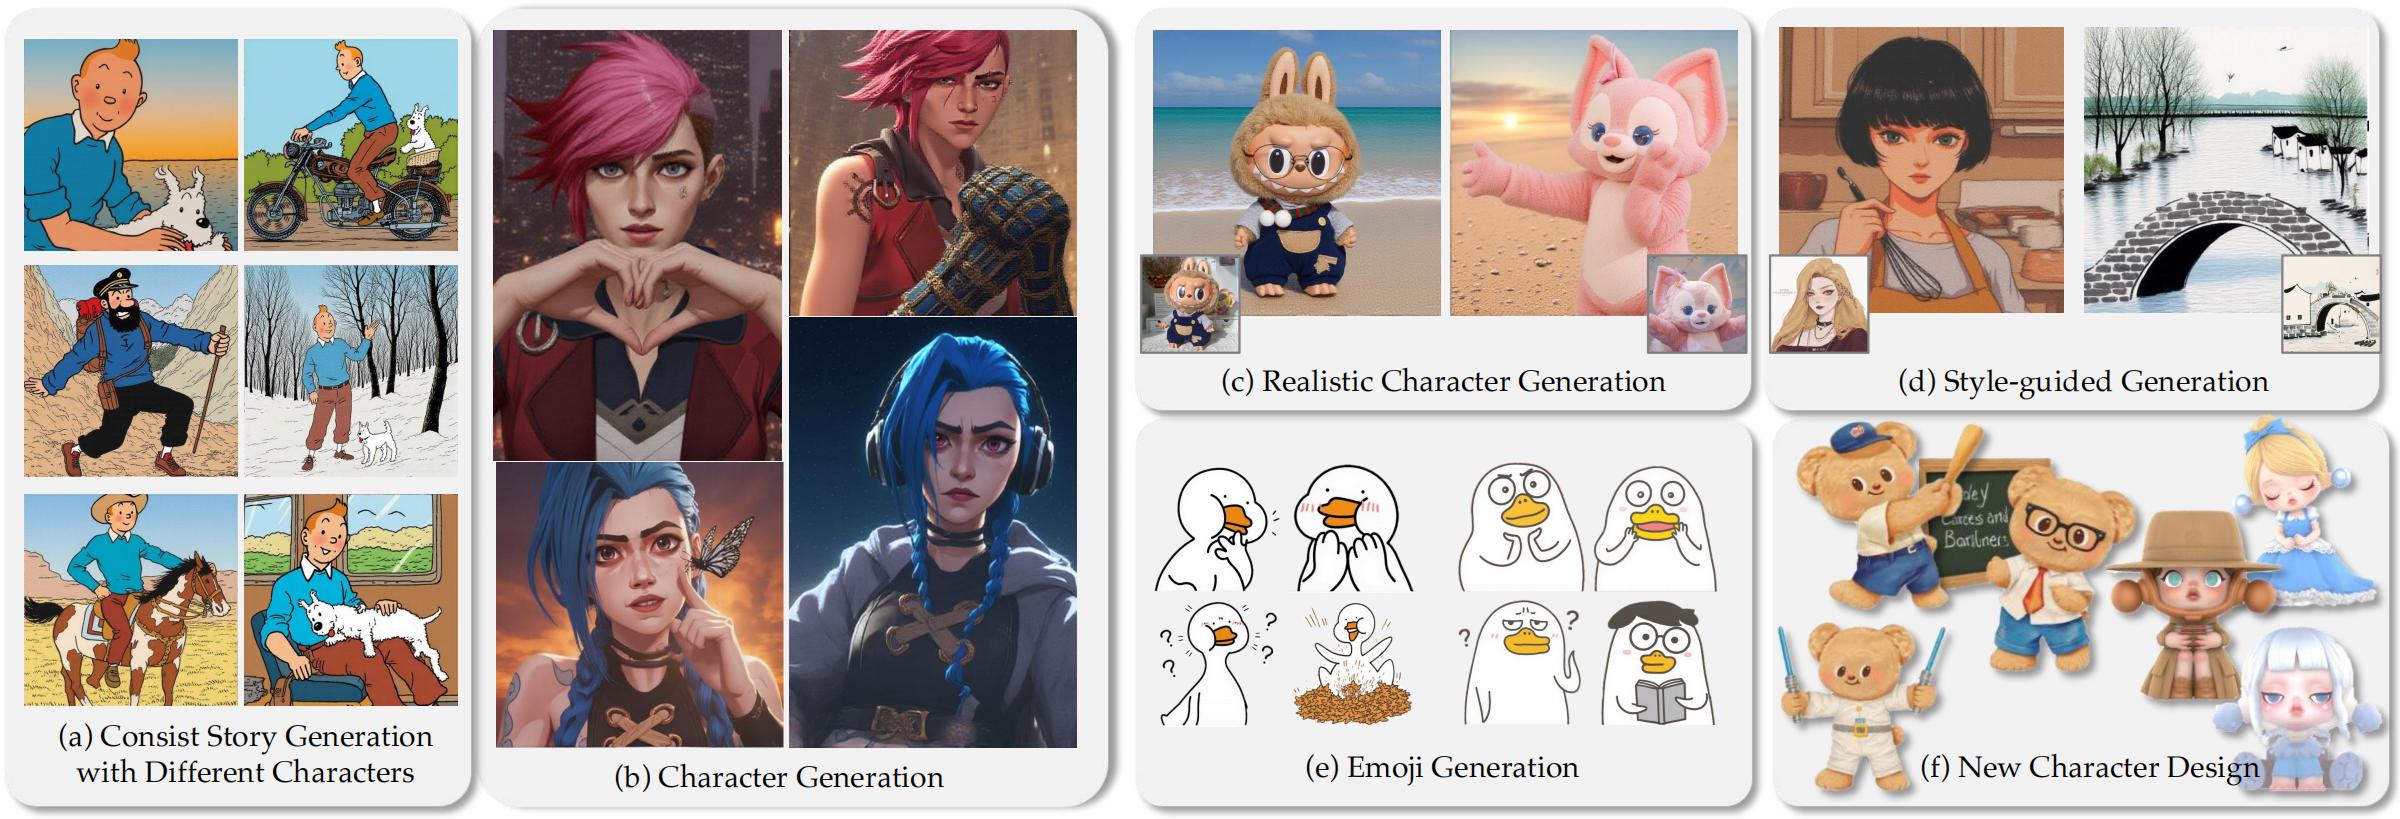
- Applications: MagicPose, IP-Prompter, and 20+ high-profile product launches (such as this one and this one).
News
- Hiring! I am hiring people interested in efficient AI (distillation, quantlization, efficient architecture design, training efficiency improvement etc) for image/video/LLM models in China. Please feel free to contact me if you are interested!
- Introducing Canva Magic Layers: transforming flat images into editable, layered designs. My team is responsible for end-to-end acceleration of the underlying models. [Canva Newsroom]
Selected Publications
-
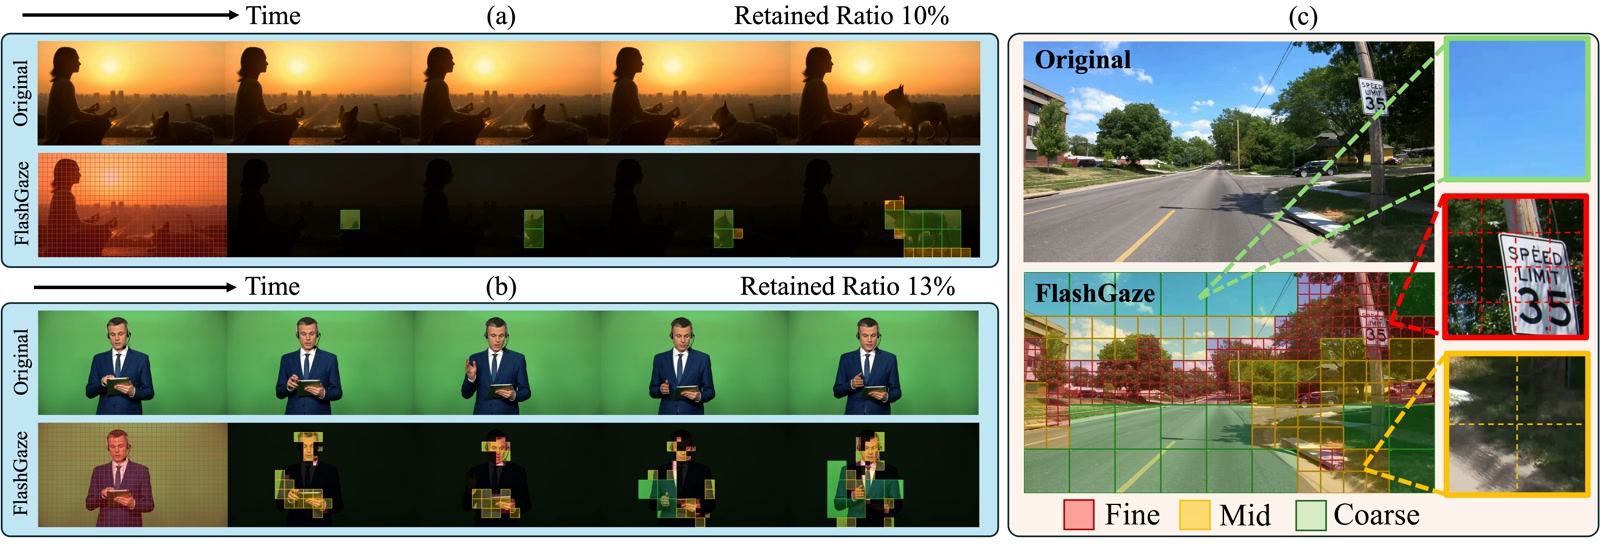
FlashGaze: Training-Free Multi-Scale Patch Pruning For Efficient Video Understanding.
arXiv 2026
Training-free patch pruning for efficient video understanding. On Qwen3-VL-8B, retains 98% of baseline accuracy on LongVideoBench with up to 5.4× faster vision encoding and 17× faster MLLM prefill.
-
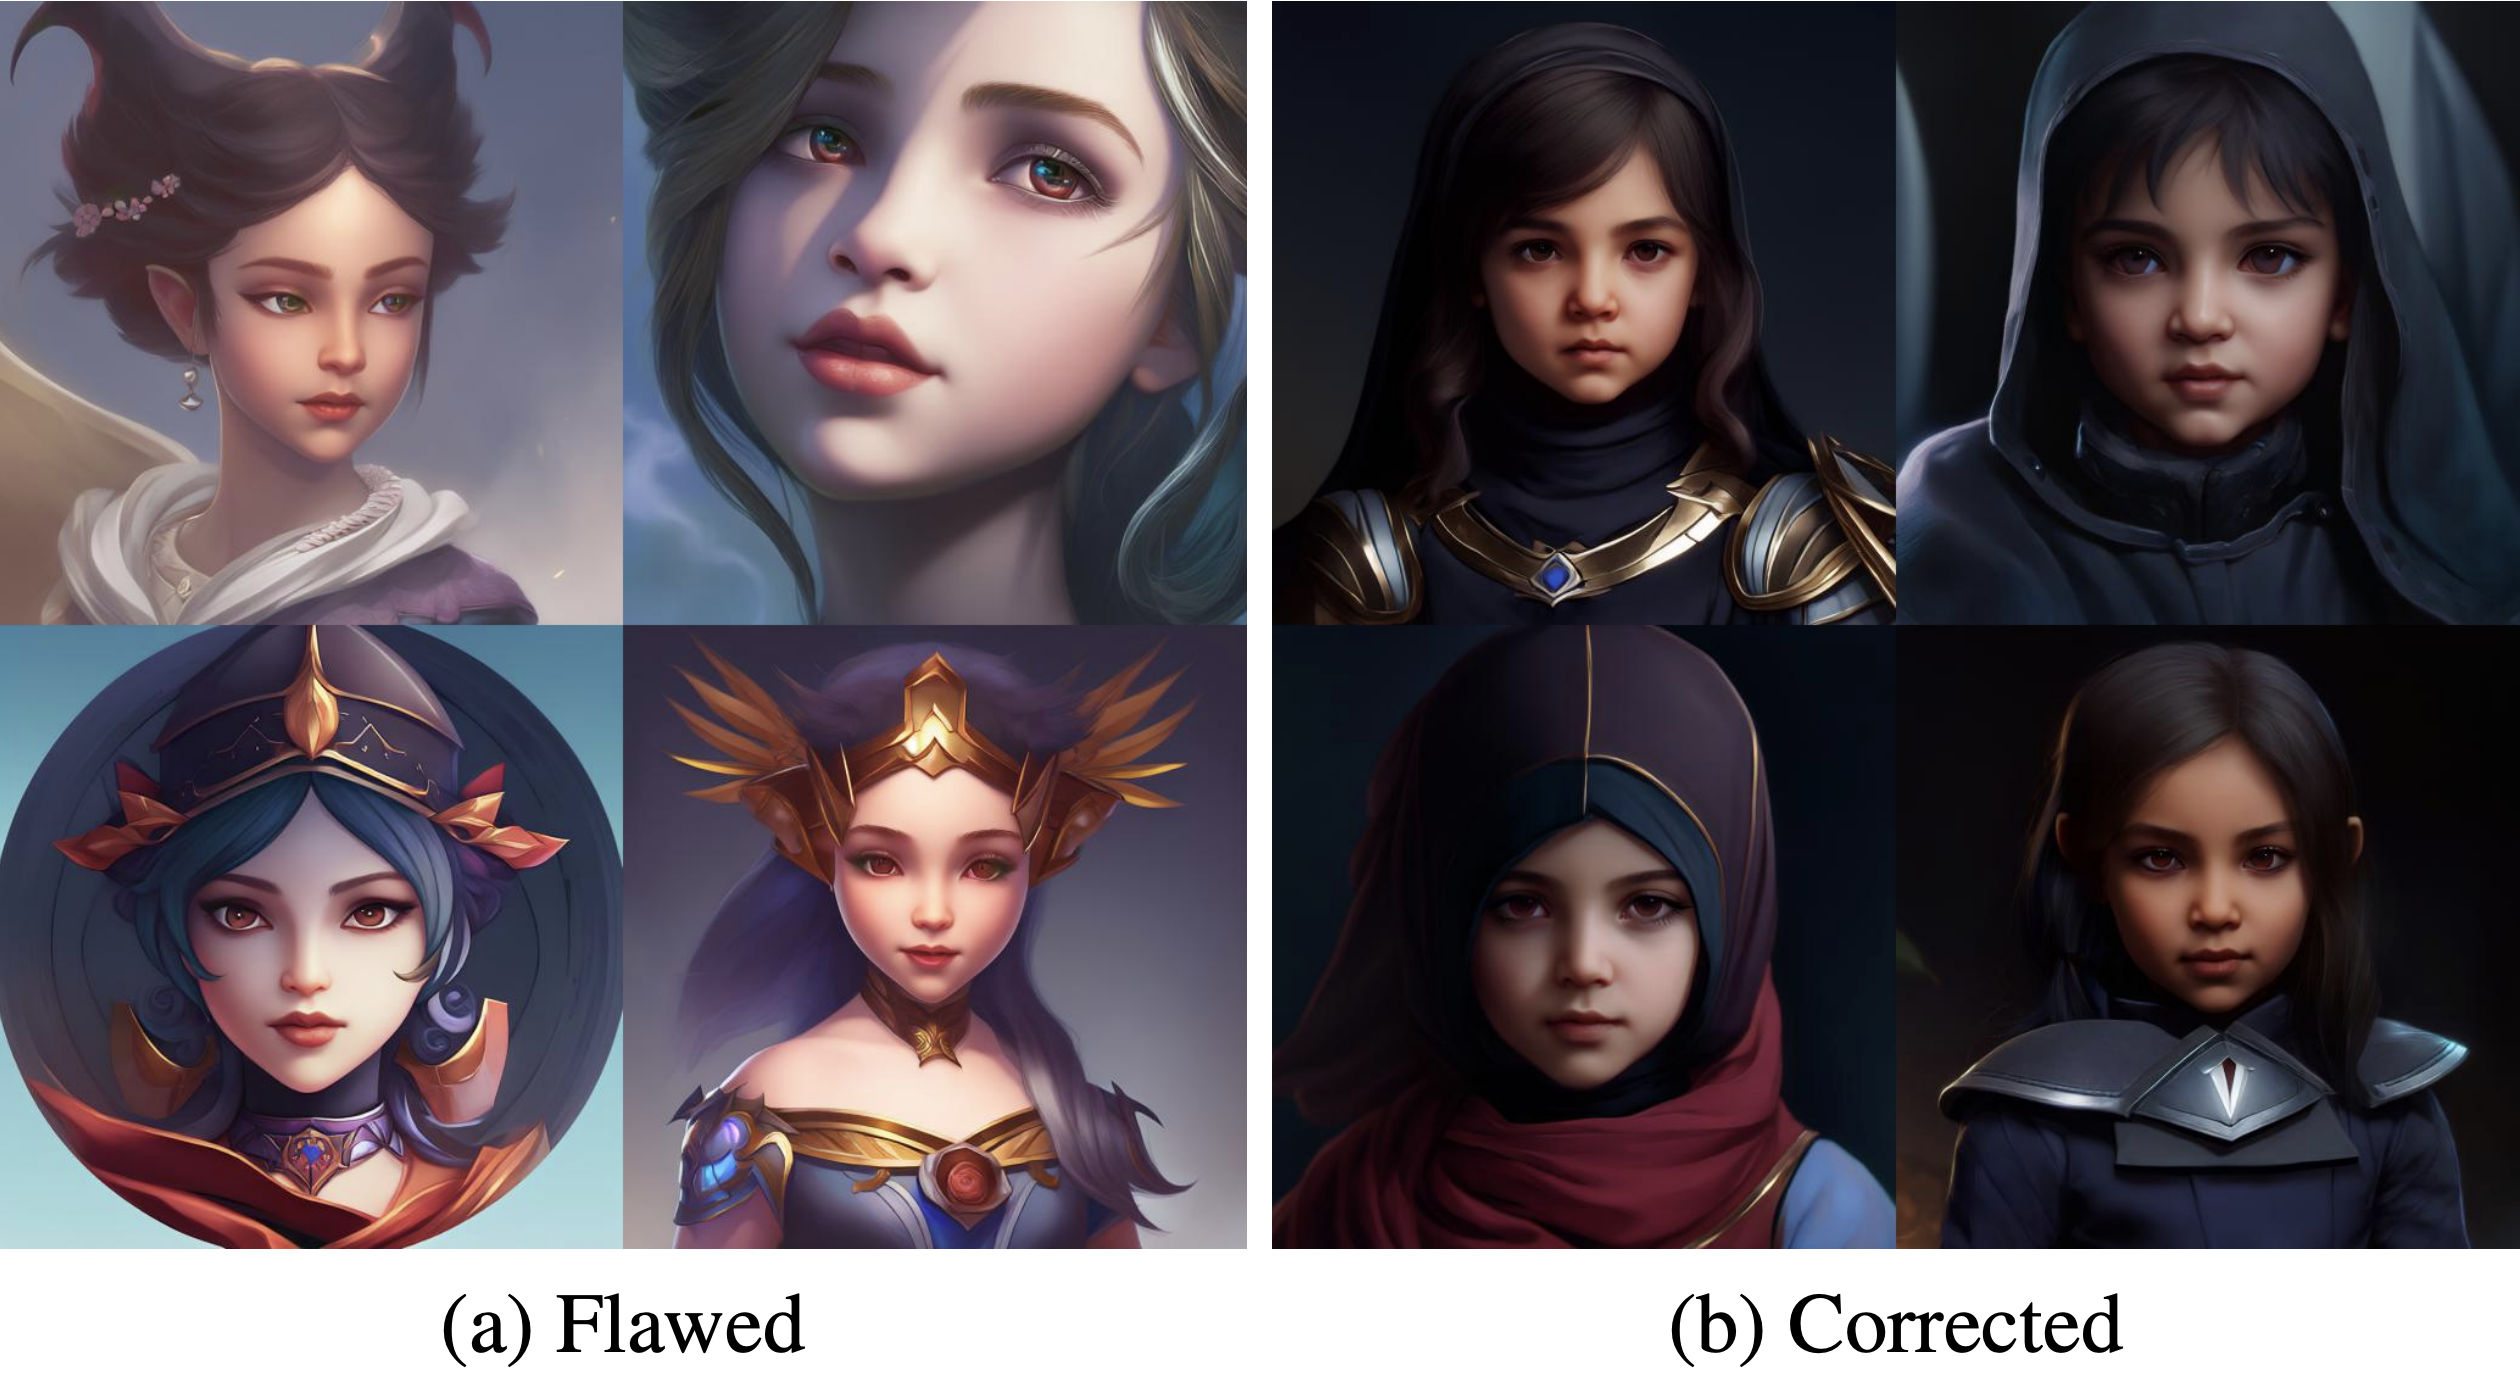
Common Diffusion Noise Schedules and Sample Steps are Flawed.
WACV 2024
Zero-terminal SNR. Widely-used noise schedule fix for diffusion model for image/video/3D generation







Last update date: 2026/10.